
On-device LLMs in your Flutter app.
No servers. No cloud. Just Dart.
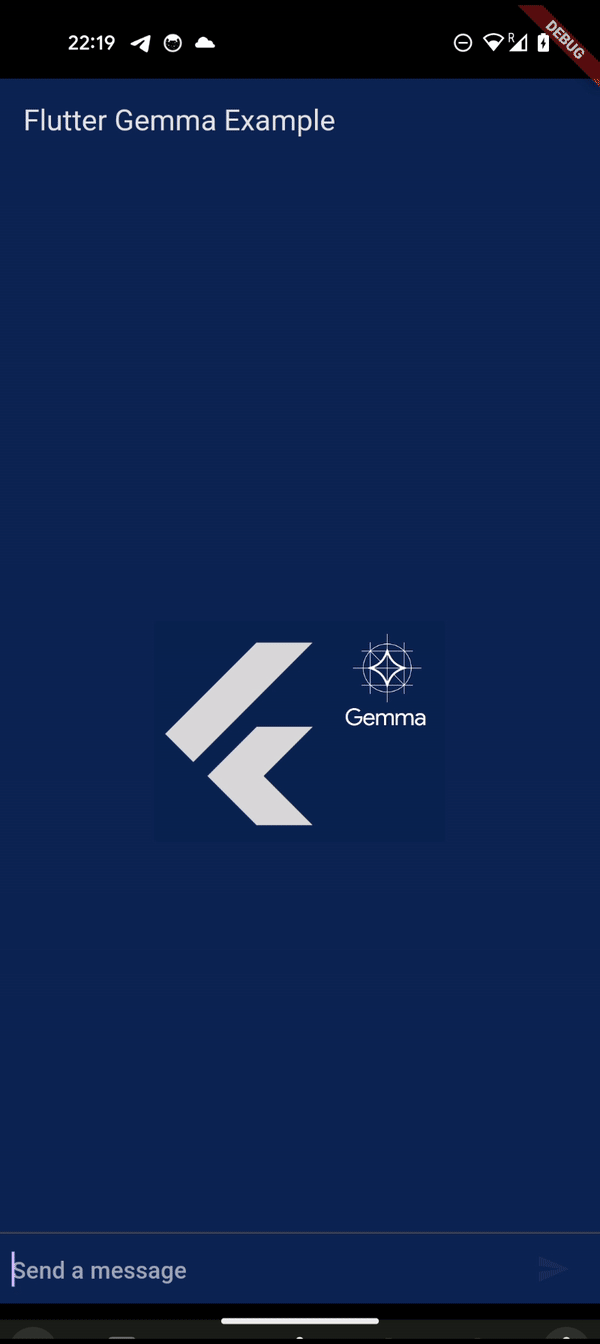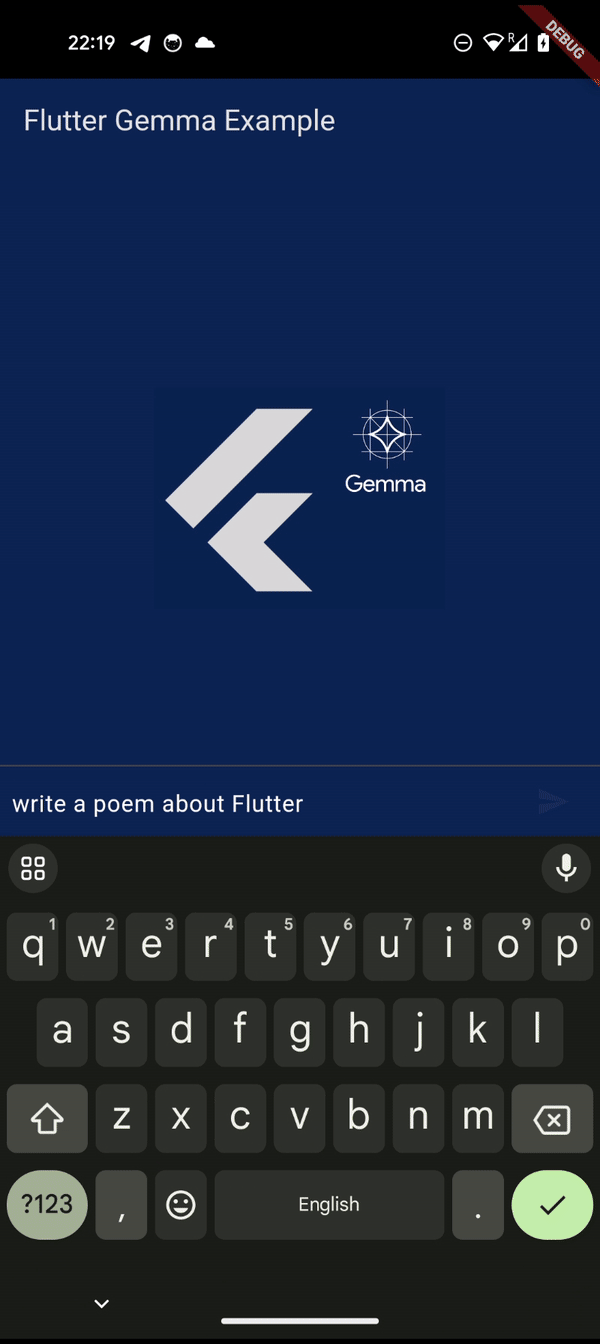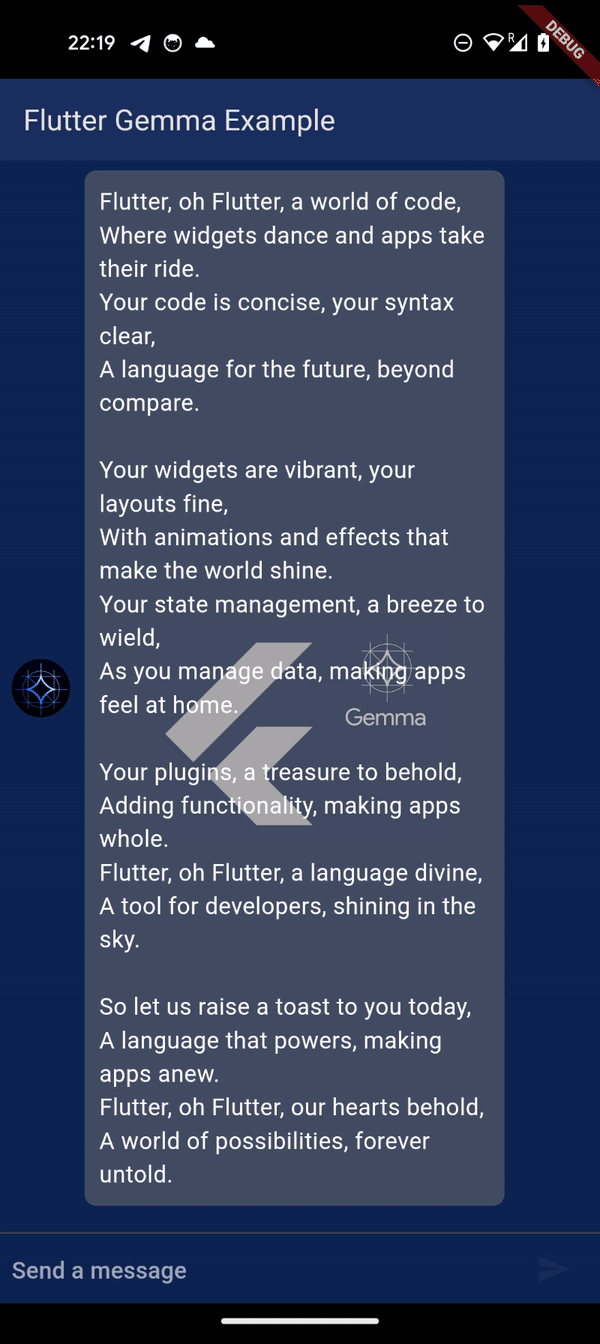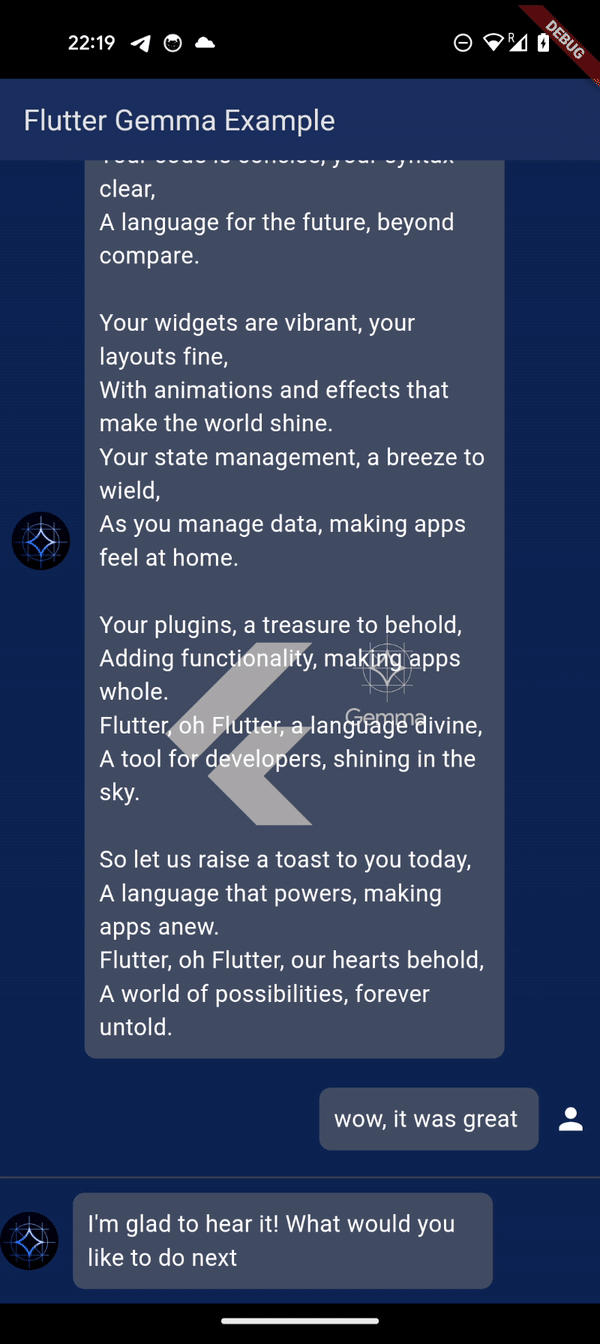
runs in your browser
Everything you need for on-device AI
Multimodal
Vision + audio input with Gemma 4, Gemma3n, FastVLM
Function Calling
Models call your Dart functions — structured tool use on-device
Thinking Mode
See the reasoning chains of Gemma 4, DeepSeek R1 & Qwen3
Agent Skills
Give the model SKILL.md skills it runs itself — JS, native intents, MCP
Speech (STT + TTS)
Transcribe audio and synthesize speech on-device — selectable models, LiteRT C API, fully offline
On-device RAG
qdrant-edge native vector store, sqlite-vec on all platforms incl. web
GPU Acceleration
Metal / Vulkan / WebGPU / DX12 — all backends covered
Built-in AI
Run Gemini Nano & Apple Intelligence — an OS-owned model, zero download
Pluggable Engines
LiteRT-LM, MediaPipe, ONNX Runtime & built-in OS AI — register the engine you need
Opt-in Packages
Core + 11 opt-in packages — agent skills, speech, RAG & more; ship only what you use
Package Skills
Claude Code, Codex, Cursor & Copilot learn the flutter_gemma API from skills shipped in the package
See it in action
Real on-device features — recorded on a phone, not a server.
Platform support matrix
| Platform | Vision | Audio | Embeddings | NPU |
|---|---|---|---|---|
| Android | ✅ | ✅ | ✅ | ✅ |
| iOS | ✅ | ✅ | ✅ | ❌ |
| Web | ✅ | ❌ | ✅ | ❌ |
| macOS | ✅ | ✅ | ✅ | ❌ |
| Windows | ✅ | ✅ | ✅ | ✅ |
| Linux | ✅ | ✅ | ✅ | ❌ |
NPU support requires Intel LunarLake/PantherLake (Windows). iOS GPU runs on Metal on device; the Simulator is CPU-only (256 MB Metal allocation cap).
5 minutes to on-device inference
Register your engines once, install a model, create a chat session — then generate. The same Dart API across all six platforms.
await FlutterGemma.initialize(
  inferenceEngines: [LiteRtLmEngine(), MediaPipeEngine()],
  embeddingBackends: [LiteRtEmbeddingBackend()],
  vectorStore: QdrantVectorStore(),
);

await FlutterGemma.installModel(
  modelType: ModelType.gemma4,
  fileType: ModelFileType.litertlm, // the declared type picks the engine
).fromNetwork('https://.../gemma-4-E2B-it.litertlm').install();

final model = await FlutterGemma.getActiveModel(maxTokens: 2048);
final chat = await model.createChat();
await chat.addQueryChunk(Message.text(text: 'Hello!', isUser: true));
final response = await chat.generateChatResponse();
Need step-by-step setup? Read the full guide →
Supported models
All models run entirely on-device. Pick by capability, size, or platform support.
Gemma 4 E2B
Next-gen multimodal — text, image & audio
Gemma 4 E4B
Next-gen multimodal — higher capacity
Gemma3n E2B/E4B
Multimodal chat — image & audio
FastVLM 0.5B
Fast vision-language on desktop
Phi-4 Mini
Reasoning & instruction following
DeepSeek R1
Reasoning & code generation
Qwen3 0.6B
Compact multilingual with thinking
Qwen 2.5
Multilingual chat
Gemma 3 1B
Balanced text — all platforms
Gemma 3 270M
LoRA fine-tuning base
FunctionGemma 270M
On-device function calling
SmolLM 135M
Ultra-compact for edge devices
Why on-device?
Privacy
Data never leaves the device
Offline
Works with no network connection
Zero cost
No API bills, no rate limits
Low latency
No round-trip to a server
Ship AI that never leaves the device.
Open source, MIT licensed, maintained by the community. Star the repo and help spread on-device AI for Flutter.